Pythia: powering Fieldguide's long-horizon agent evals

The Pythia was the high priestess at the Temple of Apollo in Delphi, and people traveled across the ancient Mediterranean to ask their hardest questions to her. Our problem is less divine, but we borrowed the name because of the one question we keep having to answer: are our agents doing work an auditor could stand behind?
We built Field Orchestrator, a custom agent harness and top-level agent that guides auditors through multi-step audit workflows. Early on the priority was speed to market. Intuition and manual testing got us to a working product, but along with that came inconsistent outputs and behavior that diverged between runs.
Those issues emerged across dozens of turns, tools, and components, so they were often hard to reproduce. Sometimes the cause was as simple as the phrasing of a system prompt. Unlike traditional software, there’s rarely one line of code to point at, so fixing agent quality means forming a hypothesis and testing it over many runs.
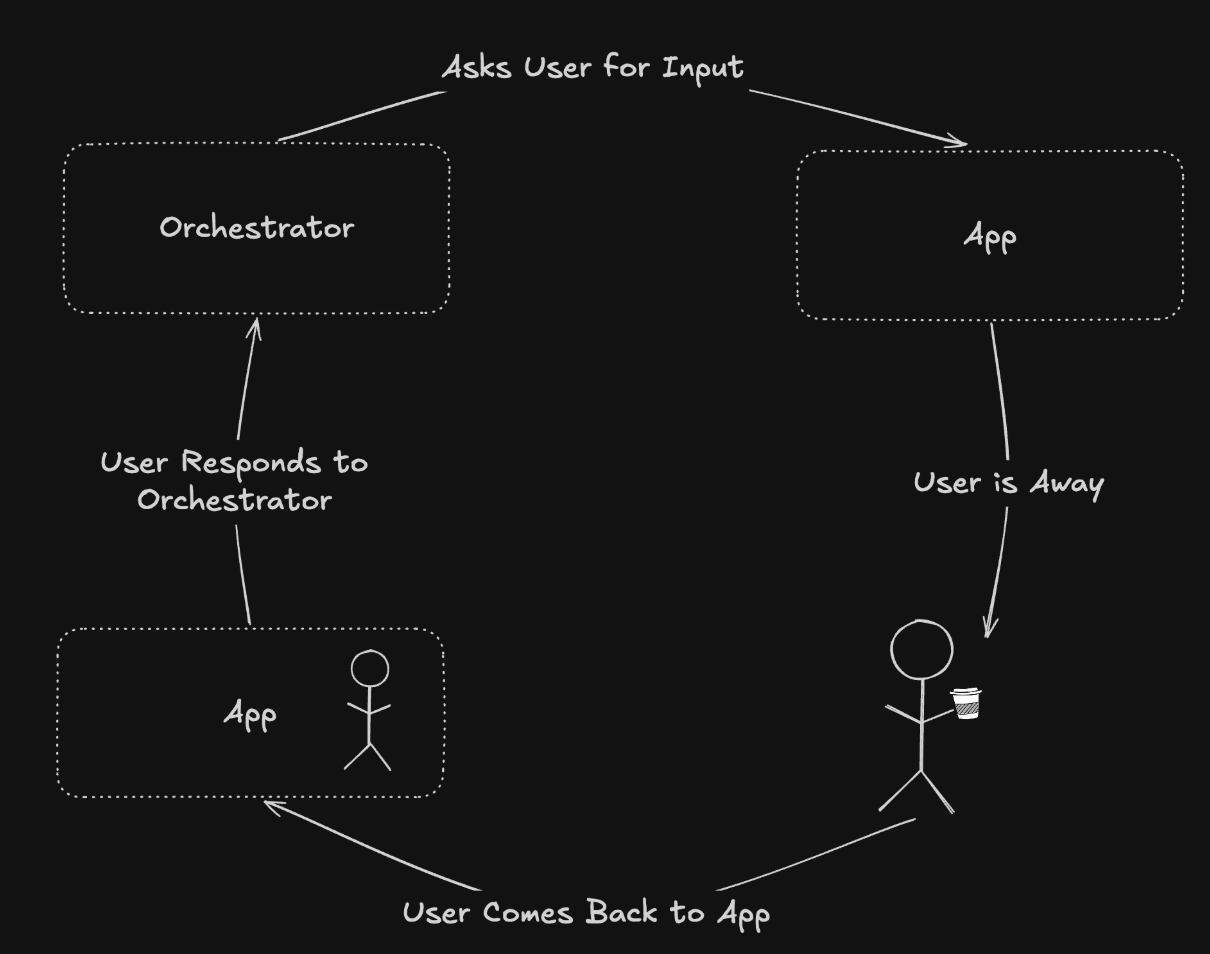
Testing a hypothesis is slow. Each phase of Field Orchestrator depends on the phases before it, so reaching the phase we care about can take many minutes and in some cases, hours. Orchestrator also needs user input between phases. Before Pythia, a person supplied everything. That’s tolerable for a few runs, but unworkable across hundreds of them.
The standard we're held to here is higher than for most software, where a review and a click-test make a feature safe to ship. In audit, a conclusion is only as good as the work it came from. Did we generate the right sample? Did we link the right documents to the right rows? Did we extract the right values out of those documents?
So the first hurdle was building up a dataset of Orchestrator runs. Every run gives us another result to evaluate, and the more results we evaluate, the more our performance analysis and hypothesis testing hold up. Generating those runs by hand is slow and painful. We needed an eval framework that could simulate everything as realistically as possible, all without a human in the loop. Pythia is how we do that.
The building blocks of Pythia
Pythia starts, monitors, and evaluates an end-to-end Orchestrator run with no human intervention. It has three components.
Ingestor marks an Orchestrator run as ground truth. This is a run our subject matter experts have vetted, and it becomes the standard every future run is measured against. Ingestor extracts the final sample sheet from that run and stores it, along with the other attributes of the scenario, for later comparison.
Conductor supplies the user inputs Orchestrator waits on. It is deliberately thin and stateless. A conductor smart enough to work around Orchestrator's mistakes would hide the exact failures we are trying to measure, so the LLM call produces only a short semantic answer, which we then convert deterministically into the payload Orchestrator expects. Most of Conductor's behavior lives outside the model call. When a run fails, we can tell which side failed.
Evaluator compares the sample sheet Orchestrator generated against the sample sheet from the ground truth run, once Orchestrator finishes. We have a system for cell-level comparison, how partial credit works, and how abstention is scored. Both sheets and the experiment result are stored in LangSmith datasets.
Each Pythia run executes as its own Temporal workflow, so it gets independent state, retries, and failure recovery.
What we can see from up here
Pythia produces the data and lets us watch the whole run. LangSmith gives us model and agent traces, Temporal gives us workflow state and retries, Datadog gives us runtime and infrastructure behavior, and the product UI gives us the user-visible outcome. Between them we can tell whether a bad result came from the Orchestrator guidance, the harness, a sub-agent, or somewhere else.
At the end of a run, Pythia outputs links to the LangSmith dataset holding the evaluator experiment and to the Temporal workflows it kicked off. We can start a batch, leave, and come back to scored results.
Because Pythia runs on Temporal, Pythia runs concurrent Orchestrator sessions per run, so we also can stress-test Orchestrator without building a separate system for it. That surfaced architectural gaps under load, and we fixed several product issues before they reached customers.
How Pythia impacts our AI quality work
Pythia makes it easy to check a change across dozens of runs instead of a few, which changes who can work on agent quality.
Here’s what we see it looking like. A designer notices that Orchestrator formats markdown inconsistently in its message output in a specific case. She researches it, forms a hypothesis, and opens a PR with a fix. Instead of testing it by hand, she uses Forge, and asks it to check the PR out into multiple sandboxes and trigger multiple Pythia runs across them.
She logs off. The next morning there is one dataset covering all runs. She can see whether the PR fixed the formatting, and the eval scores tell her whether it regressed anything else. Repeat that across many people and many days and Orchestrator improves fast with few regressions.
We also can reuse this data for Agent Knowledge, our context graph system, and future improvements that let Orchestrator learn from its own history. By labeling corrections on traces from past runs, Orchestrator can handle situations it has seen before without repeating the mistakes it made the first time.
The goal is for anyone at Fieldguide to own AI quality for the product surface they work on: propose an improvement, launch a batch of evals, and come back with evidence about whether it worked.
Closing
AI quality in long-horizon agentic workflows resembles fighting a Hydra. Fix one issue and two more appear. We don't need a Hercules for it. We need many people making small changes that each get measured, and Pythia is what makes each of those changes checkable.
Sub Sahoo
AI Engineer